Six years owning pipelines other people make decisions from: SMB client accounts, an NGO analytics cycle, and a 6B+ row warehouse across BigQuery, ClickHouse and PostgreSQL. Multi-source reconciliation, dimensional modelling, sub-500ms P90.
6+ yrs
building production pipelines
10+
SMB client accounts automated
70%
ops efficiency via tooling
About me
I am Vansh Bordia, a data engineer strongest where data arrives dirty: multi-source reconciliation across four external systems, star and snowflake schema design over billions of rows, and turning ambiguous business logic into written technical specifications that engineering delivers against.
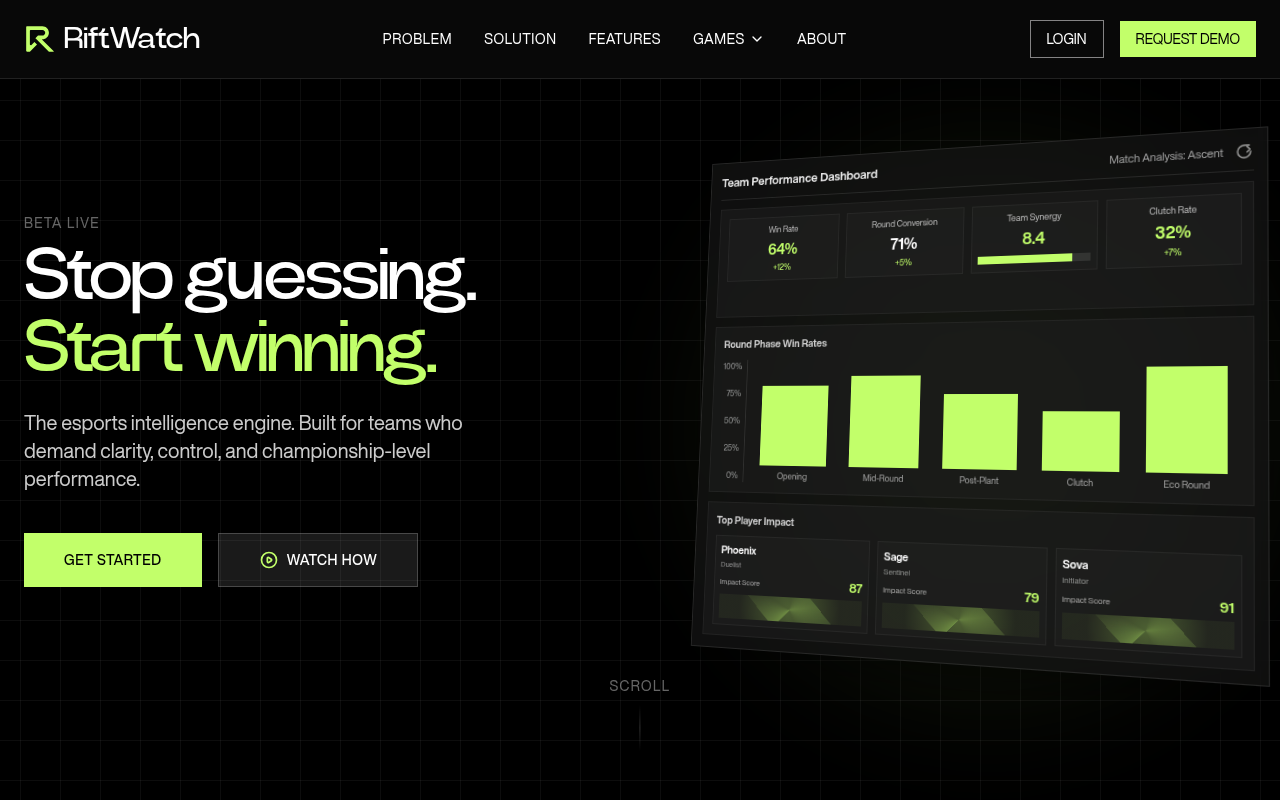
The scale has ranged from ten SMB client accounts to a 6B+ row warehouse. At a QSR client I reconciled Square POS with Uber Eats, Postmates and DoorDash, then profiled query plans instead of guessing at bottlenecks to cut order latency 40%. At an NGO I owned the whole analytics cycle with no data team, automating workflows across five teams for 70% efficiency. At RiftWatch I designed the end-to-end ETL ingesting 750+ pro matches into 6B+ analytical rows, automated validation with no manual review queue, then transferred the complete warehouse, datasets and IP to an acquiring organization with advance notice to every user.
Why me
I own pipelines other people make decisions from: client-account ETL, a full NGO analytics cycle with no data team, and a 6B+ row warehouse with automated validation and a clean handover at acquisition.
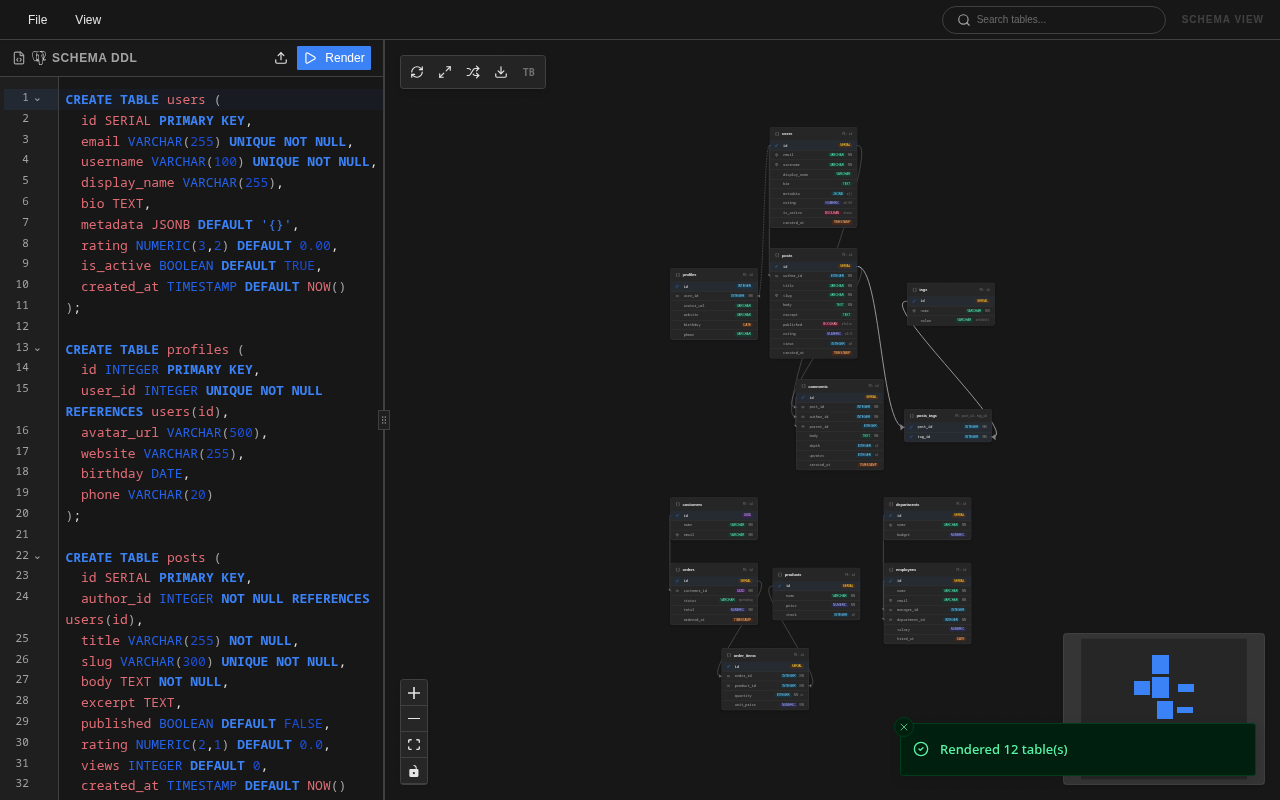
Data engineer who builds and maintains the pipelines business decisions depend on, across wildly different shapes of problem. Storage architected by workload rather than convenience: PostgreSQL for transactions, BigQuery alongside ClickHouse for large-scale analytics, Spark for distributed jobs, Redis for caching. On the reading side I work in GA4, Power BI and Looker Studio, so the pipeline and the dashboard it feeds are built by the same person.
6B+ analytical rows architected by workload: Postgres for transactions, BigQuery and ClickHouse for analytics, Spark for distributed jobs
Reconciled 4 external systems (Square POS, Uber Eats, Postmates, DoorDash) into one consistent view
Owned the analytics cycle end to end for an NGO, automating workflows across 5 teams for 70% efficiency
Automated ingestion where operators validate only anomalous records, no manual review queue
Transferred the full warehouse, ETL, models and APIs to an acquiring organization with advance notice
Role stack
SQL / Python / BigQuery / ClickHouse / PostgreSQL / Apache Spark / Google Cloud / Dataflow / Cloud Composer / Dimensional Modeling / Star & Snowflake Schema / Schema Evolution / Partitioning & Clustering / Query Plan Analysis / Multi-Source Reconciliation / Data Quality / ETL Orchestration / Power BI / Google Analytics 4 / Looker Studio / Excel / Tableau / A/B Testing / Statistical Analysis / Reporting
Relevant work
RiftWatch
Esports intelligence platform, acquired by a pro org
750+ pro matches processed into 6B+ analytical rows in ClickHouse
20 orgs at peak including Tier-1 across Americas and EMEA
VALORANT-specific Gemma models plus RAG over live patch data
Agentic harness routing tools, models and queries; sub-500ms P90